Pilot-to-Production Review sample
What the review delivers, shown on a real system.
The four-part operating design a two-week review produces, filled in with StreamGist's recommendation system. A client version covers one of your workflows.
1. Operating design
Who decides what.
Code owns anything that could corrupt data, spend, or production. Models do bounded judgment and writing. People own the rules and the irreversible calls.
2. Failure modes and fallbacks
What still works when something breaks.
Each failure has a planned fallback before launch, not after the incident.
- Model provider down or wrong
- Ranking never calls a model, so recommendations keep serving.
- Research fails for one game
- Atomic writes keep its last good state. Other games continue.
- A model changes behavior
- Requested and served models are logged. Replays come before any switch.
- A wrong score spreads
- Drift monitoring watches tags, rankings, and copy.
- Feedback only sees what it showed
- Cohort controls and fixed experiments separate quality from exposure.
- A job stalls quietly
- Every job is checked every ten minutes. Unknown is never reported as zero.
3. Success metrics and baseline
What gets watched.
Every metric has an owner and a baseline before anything changes.
- Research cost per completed game
- Score and tag distribution drift
- Save rate by cohort vs. the 21.4% baseline
- Job freshness, failed writes, rollbacks
- Reviewer holds and founder edit burden
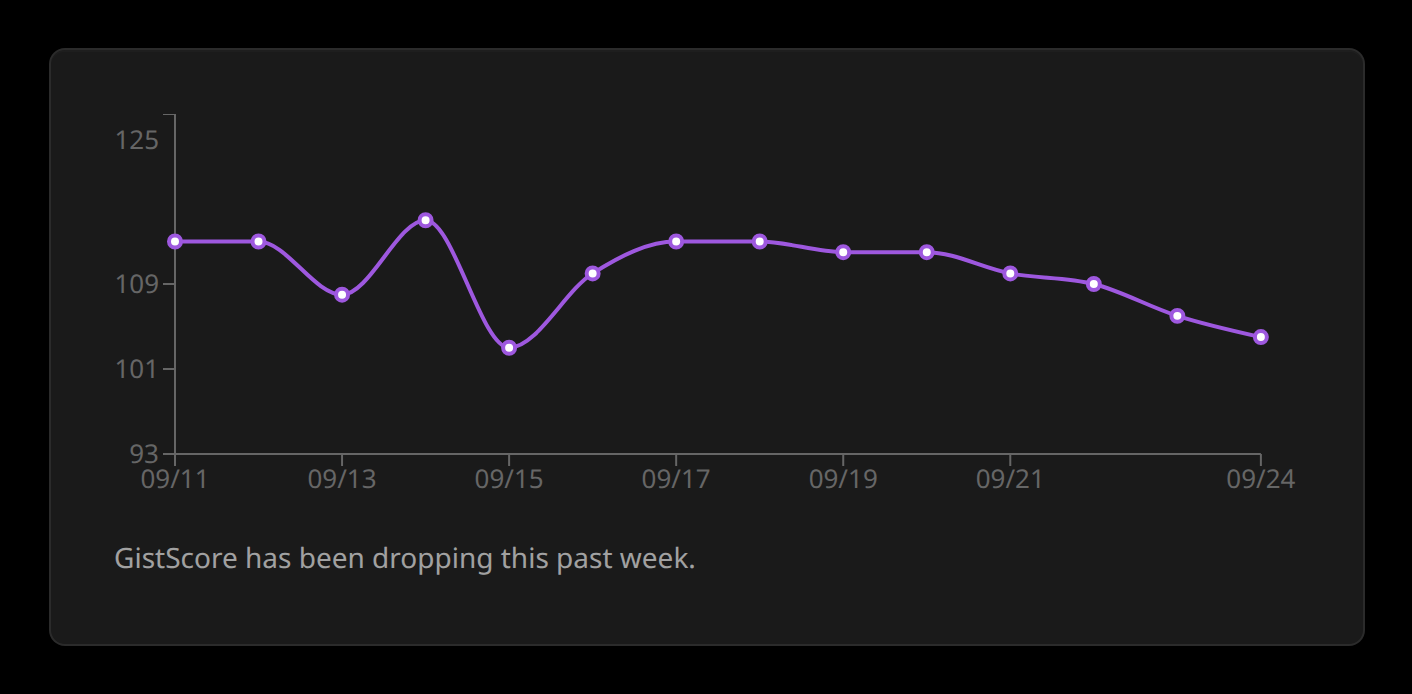
4. Go/no-go readout
StreamGist's own call.
A client readout adds a 90-day roadmap sequenced from findings like these.
Authority boundaries and evidence lineage held up. The adaptive recommendation loop needs production evidence, not another redesign.
Reopen only on
- A repeated production failure
- A measured cost concentration
- A frozen replay that shows a gap
Want this for one of your AI workflows?
Two weeks, one workflow. Write a few sentences about it and I will follow up.